AI pilots are designed to answer one question: can the use case work? Production asks a harder set of questions. Can the platform serve many users? Can retrieval keep pace with inference? Can analytics and deep learning share infrastructure without starving critical applications? Can the environment expand without rebuilding the stack? These are AI factory infrastructure questions, and the server layer sits at the centre of them.
Production AI Is a Portfolio of Workloads, Not One Model
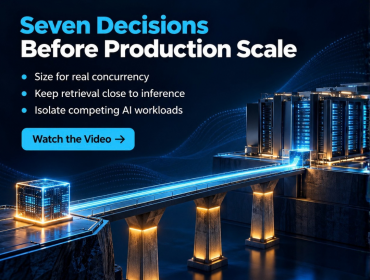
The first decision is workload mapping. LLM inference is sensitive to model size, context length and concurrency. RAG adds retrieval and data movement. Analytics may need large memory and high storage throughput. Deep learning can occupy several GPUs for long training runs. The server architecture has to reflect this portfolio rather than a single benchmark.
Second, capacity planning should be based on concurrency. A model that responds quickly to one user can behave very differently under many simultaneous requests. Production AI servers need enough accelerator headroom and memory to maintain service levels as demand rises.
Third, RAG requires the data path to be considered alongside inference. Retrieval quality matters, but so does retrieval speed. The server, vector database, storage layer and network have to work together so the model is not waiting for context.
Fourth, GPU density has to be balanced with host memory and CPU capability. Large pipelines perform preprocessing, retrieval, analytics and orchestration outside the GPU. Under-sizing those layers can create a bottleneck even when accelerator capacity looks strong on paper.
Fifth, local and shared storage should be planned as one data architecture. Local NVMe can help with active datasets, model files and checkpoints, while shared enterprise storage supports broader data access and collaboration. Different workloads will use these layers differently.
Sixth, mixed workloads need scheduling and isolation. A long deep learning job should not unexpectedly consume resources required by production inference. AI factory infrastructure therefore needs an operating model for who gets what capacity and when.
Finally, the server layer should be treated as one part of the AI factory. Compute, storage, networking, orchestration, security and monitoring need a common scale path. When these decisions are made together, enterprises can add AI services without creating a new infrastructure silo for every project.
| Explore Tyrone Camarero AI server options for LLM inference, RAG, analytics and deep learning: https://tyronesystems.com/servers/RDA200A2G-424.php |
7 AI Factory Server Decisions Before Enterprise AI Goes Production-Scale
A successful AI pilot does not prove the production infrastructure is ready. LLM inference, RAG, analytics and deep learning introduce different demands for GPU capacity, memory, storage and orchestration. Watch the video for seven server decisions to make before enterprise AI moves to production scale.
Get in touch info@tyronesystems.com