How enterprises can plan compute, cooling and throughput before AI demand peaks
Scaling LLM workloads is not only a model decision. It is an AI Infrastructure decision that affects power, cooling, networking, storage and operations.
Many enterprises discover this too late—after AI pilots expand into production demand and the existing data centre infrastructure can no longer keep pace.
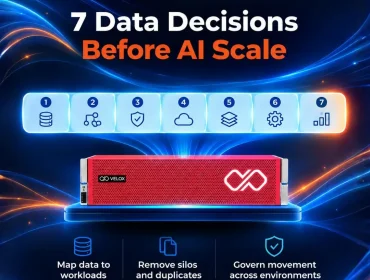
➤ Question 1: What Is the Workload Size?
The first step is understanding the workload. Enterprises need to determine whether their LLM infrastructure will support experimentation, fine-tuning, large-scale training, inference or a combination of AI workloads.
Understanding workload requirements early helps organisations plan compute capacity around both current demand and future AI growth.
➤ Question 2: How Dense Is the Compute?
Compute density is a critical consideration for enterprise AI. AI workloads require servers capable of sustaining demanding jobs rather than delivering short bursts of performance.
As GPU-intensive workloads increase, enterprises must evaluate server capacity, rack density and infrastructure requirements together.
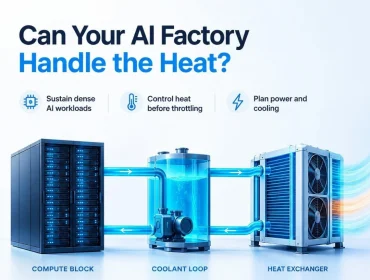
➤ Question 3: How Will AI Workloads Be Cooled?
As AI-optimised servers become more power dense, thermal management becomes increasingly important.
Liquid cooling provides enterprises with an effective approach to managing heat in high-density AI environments while creating a stronger foundation for future expansion. Cooling should therefore be part of AI Factory planning from the beginning, rather than a reactive upgrade.
➤ Question 4: Can the Network Keep Up?
Distributed AI workloads depend on high-speed networking and interconnects so GPUs, CPUs and compute nodes can communicate efficiently.
Without sufficient network performance, even powerful AI servers can become constrained by data movement. Enterprise AI infrastructure must therefore be designed so compute resources can operate as one coordinated system.
➤ Question 5: Can Storage Deliver Data Fast Enough?
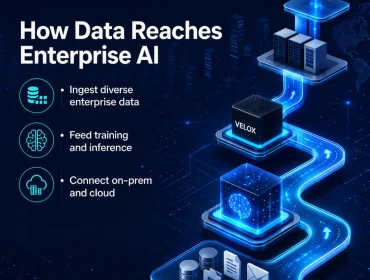
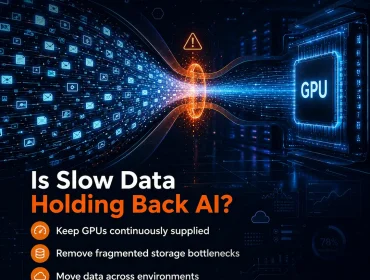
Powerful servers can still underperform when data cannot reach them quickly enough.
AI storage infrastructure needs to provide the throughput required for continuous data movement across training and inference pipelines. Storage performance should be planned alongside compute, networking and GPU capacity.
➤ Question 6: What Level of Redundancy Is Required?
AI Factory infrastructure must be designed around uptime, power resilience and operational continuity.
Enterprises should evaluate redundancy across critical infrastructure layers to ensure AI workloads can continue operating as demand grows and production becomes increasingly dependent on the platform.
➤ Question 7: What Business Outcome Will Scaling Deliver?
The final question is business value.
AI Infrastructure should not scale in isolation. It should scale alongside model development velocity, production conversion, workload demand and measurable enterprise outcomes.
When these questions are answered early, liquid-cooled AI Factory design becomes a strategic roadmap rather than a reactive data centre upgrade. The goal is not simply to add more servers. It is to build an AI infrastructure platform that can scale with the organisation, its workloads and its business ambitions.
Liquid-Cooled AI Factories: 7 Questions Before Scaling LLM Workloads
Liquid-cooled AI Factories are becoming part of enterprise infrastructure planning as AI workloads grow heavier. Watch our latest video for seven questions every team should answer before scaling LLM workloads across compute, cooling, storage and networking.
Get in touch info@tyronesystems.com