A faster cluster does not automatically mean faster results. The management decisions around it often decide how long users wait before compute becomes useful.
Why Cluster Operations Matter as Much as Raw Compute
A cluster can be technically powerful and still feel slow to the people using it. Time-to-compute depends on more than processors, memory and interconnects. It also depends on how consistently nodes are prepared, how workloads are prioritised, how quickly health issues are identified and how much manual effort sits between a request and useful execution.
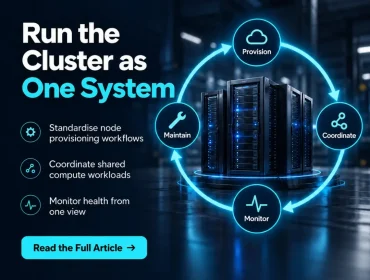
1. Standardise node provisioning — Inconsistent node builds create friction before a workload even reaches the queue. Standardised provisioning gives administrators a repeatable way to prepare compute resources with the expected operating system and configuration. That reduces configuration drift, shortens troubleshooting and helps new or rebuilt capacity become usable without creating a separate setup process every time.
2. Define workload policies early — Shared clusters need clear rules for queues, priorities and access. Without them, users compete for resources through manual intervention or unclear conventions. Workload policies create a predictable path for different job types and user groups, helping administrators decide which workloads run first and how shared compute should be allocated when demand exceeds immediately available capacity.
3. Monitor cluster health centrally — A node that is unhealthy, unavailable or degraded reduces effective cluster capacity even if it still appears in the installed hardware count. Central monitoring helps administrators see node and service status from one operational view, identify problems sooner and understand whether queue pressure is being caused by real demand or by capacity that has quietly dropped out of service.
4. Reduce manual hand-offs — Every approval, configuration request or administrator dependency can become an invisible queue. If routine access or cluster changes always require the same small operations team, users can wait even when compute is available. Reducing unnecessary hand-offs makes the operational path more direct and lets skilled administrators focus on exceptions instead of repetitive coordination.
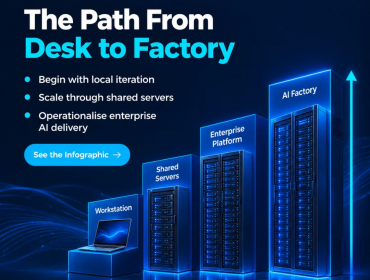
5. Plan for changing capacity — Clusters rarely stay static. New nodes are added, older systems are replaced and workload patterns change. The management model should be able to absorb those changes without forcing teams to redesign the operating process. A repeatable way to discover, provision and monitor additional nodes helps expansion feel like an extension of the current environment rather than a new project.
6. Make workload visibility actionable — Queue data is useful only when teams can explain why jobs are waiting. Long waits may come from resource requests, queue policy, unavailable nodes or a mismatch between the requested configuration and free capacity. Administrators need enough context to decide whether to change policy, address a node problem, tune a workload request or consider additional capacity.
7. Measure time-to-compute — Peak performance describes what the cluster can deliver under ideal conditions; time-to-compute shows how quickly users actually reach useful execution. Tracking the path from request or job submission to running workload exposes friction across provisioning, scheduling, health and administration. It gives infrastructure teams a user-facing metric for whether cluster operations are improving. HPC Cluster Management Software provides the operating layer that connects these decisions. Tyrone Cluster Manager documents web-based cluster management, workload management, graphical monitoring and node health checks, with additional dynamic workload management in the Advanced Edition. The practical objective is to turn installed compute into accessible compute with fewer delays between capacity and productive work.
7 HPC Cluster Management Decisions That Determine Time-to-Compute
Peak FLOPS do not tell you how quickly a researcher or engineer gets useful compute. Provisioning, queue policies, monitoring and operational hand-offs all shape time-to-compute. This slideshow highlights seven cluster-management decisions that can remove friction between available capacity and actual workload execution.
Get in touch info@tyronesystems.com