One successful GenAI demo can hide a much harder infrastructure question: what happens when the workload stops being one model, one user and one request at a time? As enterprises add text-to-image, text-to-video, fine-tuning, inference and AI agents, the pressure on GPU infrastructure changes quickly. The server layer has to support not only more compute, but different patterns of compute.
From One Model Demo to a Mixed GenAI Workload
-
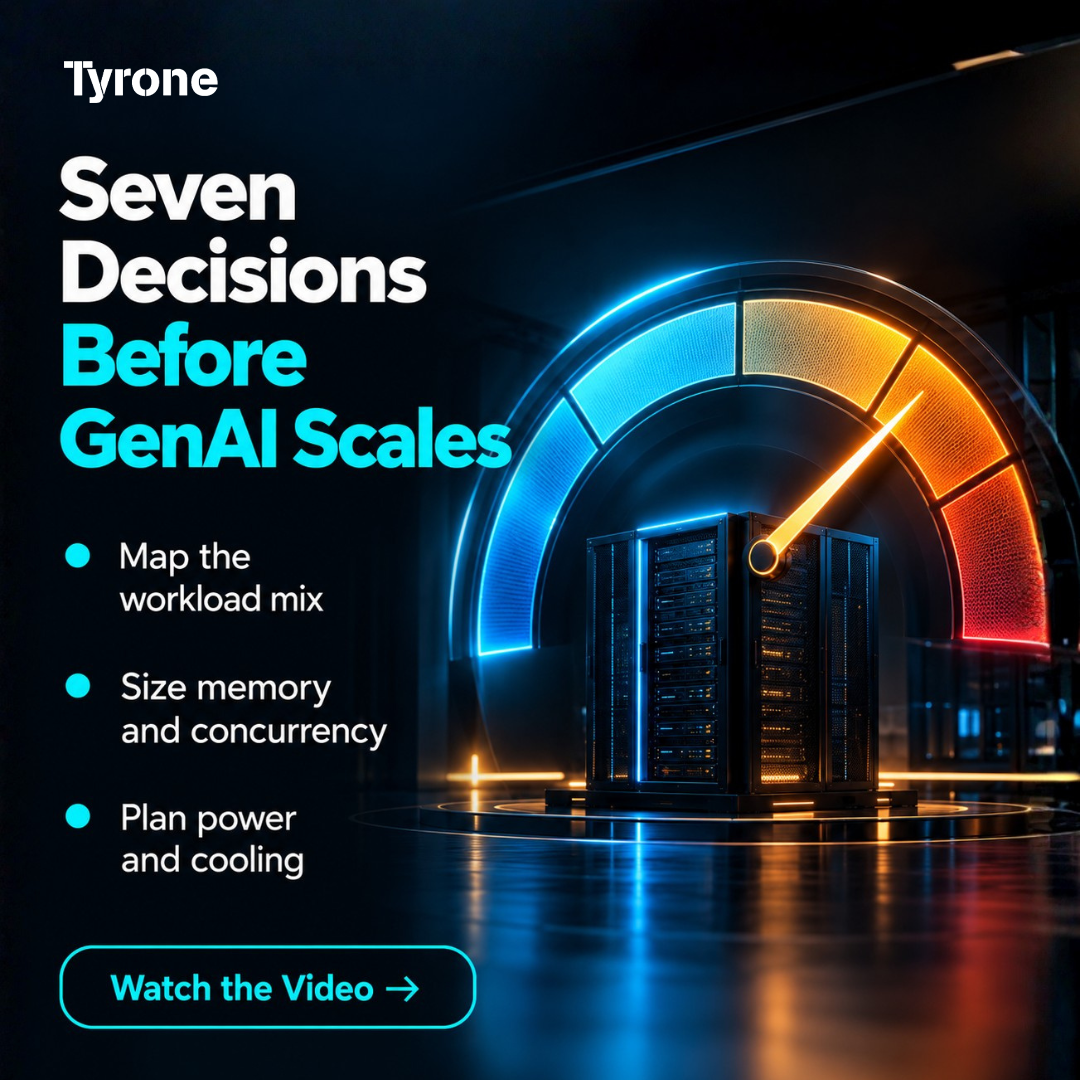
- The first decision is to map the actual workload. Training and fine-tuning create long-duration GPU demand. Text-to-image and text-to-video can require significant memory and repeated GPU processing. Interactive inference puts latency and concurrency at the centre. Agentic AI adds another layer because a single user request may trigger multiple inference calls, retrieval steps and tool actions. Treating all of these as the same “AI workload” can lead to poor sizing decisions.
-
- The second decision is GPU memory. Model size matters, but so do modality, precision, batch size and output requirements. A team generating short images has a different profile from a team generating video or running multiple models simultaneously. The right question is not simply how many GPUs are installed; it is whether the GPU memory and aggregate throughput fit the workload mix.
-
- Third comes concurrency. A prototype usually proves that a model can run. Production has to prove that many people, applications or AI agents can use it without response times collapsing. This makes inference capacity planning as important as training performance.
-
- Fourth, the GPUs need a balanced platform around them. CPU performance, system memory, fast local storage and networking determine how efficiently models and data reach the accelerators. If the rest of the server cannot keep pace, expensive GPUs spend time waiting.
-
- Fifth, enterprises need to decide where an AI workstation is sufficient and where a shared GPU server becomes necessary. Workstations are valuable for local development and focused experimentation. Server-class platforms become relevant when workloads are shared, long-running, GPU-dense or tied to production services.
-
- Sixth, power and cooling must be part of the architecture, not an afterthought. High-density GPU servers are designed to operate under sustained load, which means facilities planning matters to real-world performance and availability.
-
- Finally, infrastructure should leave room for the next workload. GenAI is moving quickly from text toward multimodal models and agentic AI. A balanced GPU server foundation can help teams absorb that change without rebuilding the environment for every new use case.
| Explore Tyrone Camarero for GPU-dense generative AI deployments: https://tyronesystems.com/servers/PDA200E1MG-48.php |
🖥️ GPU Server Decisions
7 GPU Server Decisions Before Scaling Text-to-Image, Text-to-Video and Agentic AI
Multimodal GenAI changes the infrastructure equation. A server that handles one model demo may struggle once image generation, video generation, fine-tuning, inference and AI agents start competing for the same resources. Watch the video for seven GPU server decisions to make before scaling.
Get in touch info@tyronesystems.com